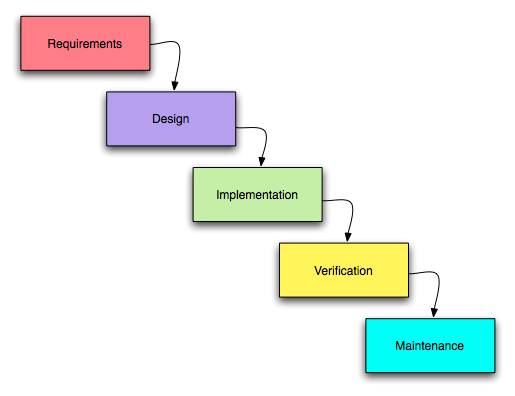
Traditionally, large software engineering projects have been managed with the “waterfall” method, where engineers figure out software requirements first, which inform their design, which informs their implementation, which informs their testing, deployment, and maintenance. This process is not really iterative: after specing a piece of software at a high level, you assume this is how it’s going to be going forward. (Just take a look at old government software or the my.pomona.edu portal.)
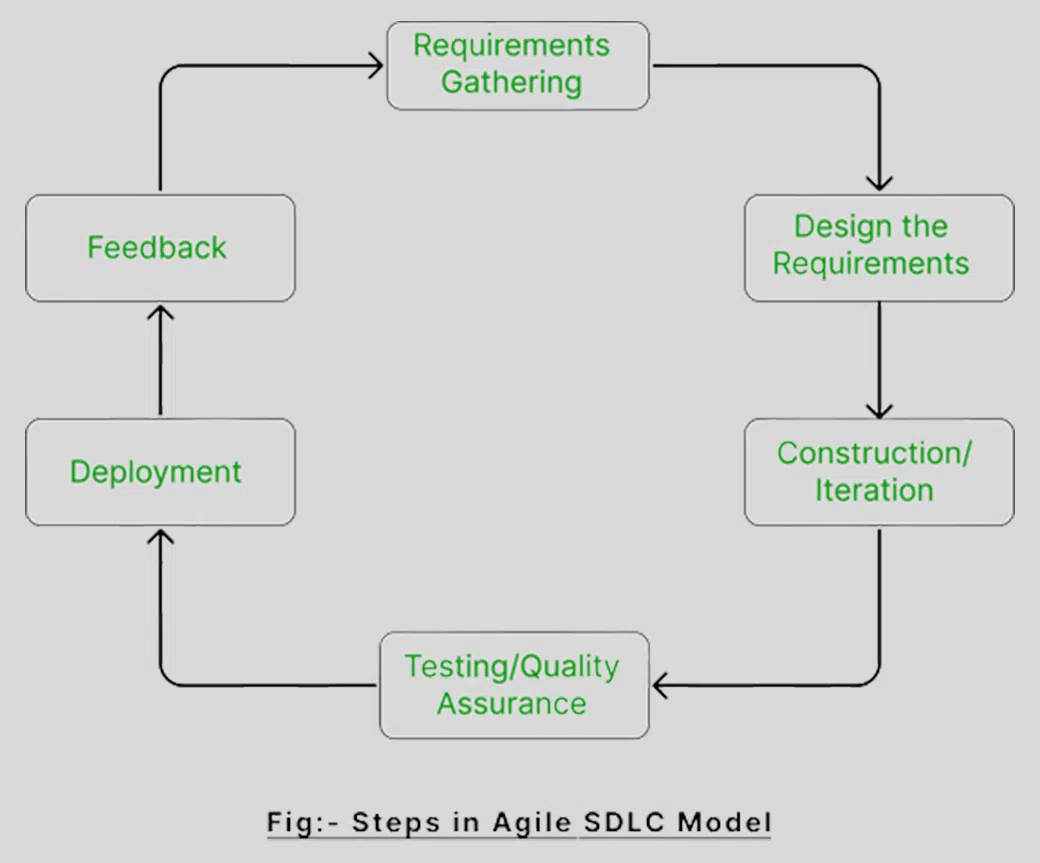
More recently, modern companies largely use the “agile” method of software development. The agile method takes lessons from iterative feedback loops of human-centered design to incorporate user feedback in software engineering. The focus, however, is more on developing software quickly: engineers go through one iteration of this loop often in 2-4 week “scrum” sessions.
Human-centered design, on the other hand, (also known as user-centered design), places the emphasis on the end user of the software, not just the software requirements or specifications.
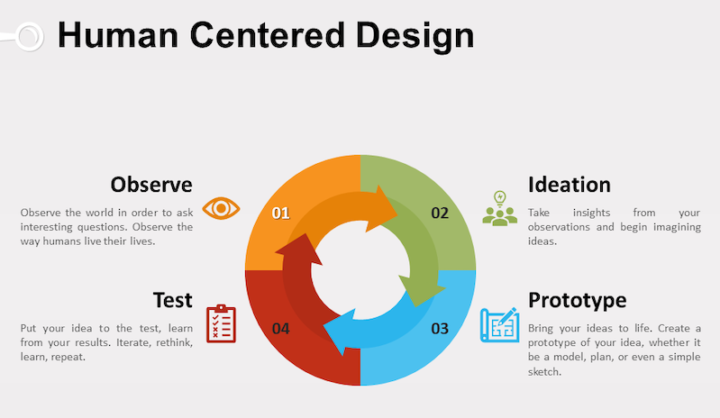
For this project, we will be trying to gear the project development towards a human-centered design. You will not be evaluating or iterating on your software project due to time constraints, but we will try and work towards quickly developing a prototype, rather than spending a long time on requirements.
Before getting into the detailed steps, here are two sample projects. I imagine your projects will fall into one of two categories: interactive software (interaction from reading user input from main() is fine) or data analysis. If you feel like your proposal falls in a different category, that’s totally fine, just check with the instructor.
Bella makes playlists they want to share with their friends, but they use Spotify while friend A uses Apple Music and friend B uses YouTube Music. While interviewing their friends and asking for stories about their music sharing experiences, they learned about turntable.fm, a (now-defunct) website that let users take turns live DJing and queuing songs for each other. Inspired by this anecdote, but still wanting asynchronous, any time music sharing in the form of playlists, Bella decides to build a Java app that will take as input a text file of Spotify or Apple Music or YouTube Music links, allow users to re-order songs in their app, and generates text files of the playlist in all 3 music sharing formats.
First, Bella’s group writes code to automatically extract song information (like Title, Artist, Album) from a given link using the Jsoup library. They use this library to also find the URLs on other music providers through parsing their search query (e.g., once given a Spotify link like https://open.spotify.com/track/6LgJvl0Xdtc73RJ1mmpotq, they scrape the title and artist to be Paranoid Android by Radiohead. They then can format a YouTube search URL like https://www.youtube.com/results?search_query=paranoid+android+radiohead and scrape the first result to get the URL to the YouTube video corresponding to the song).
Bella’s group creates a custom Song data structure to contain all 3 links, as well as song metadata. They create a custom equals() and hash function which only looks at song metadata instead of the URLs. However, they realize the best data structure to store their songs in is not a hashtable but a doubly linked list (DLL), since the songs need to be ordered as a playlist. Their DLL supports moving songs around, and they also use a queue to implement the “add to queue” feature that asks the user for a new song URL which will output the song before the rest of the playlist.
The interactive main() of their Java app prompts users to input the name of a .txt file containing song URLs in playlist order. It then parses and prints the URLs of the other streaming services. Users can use their keyboards to order songs, add new songs to the queue, or save output.txt files for the other streaming services.
Alex, David, and Marina like comparing how much money they spent at the end of the month on their group chat. They wonder: why not just build a shared group finance Java app, that takes as input spreadsheets each of them download from their bank, and outputs some data analysis (e.g., who spent the most on eating out this month? How far apart was each of their spending from each other in each category? If the group set a budget to collectively spend less than $100 on entertainment, did they make it? What was each person’s top 3 spend categories, and did it differ between them?)
From their interviews where they asked their friends to share and reflect on their past month’s spending, they learn that some friends don’t track their spending at all (and wished they did, as they found recurring subscription services they don’t use), and some friends wanted to share with other friends but were too shy to overcome the social barrier of talking about finances, while some friends wanted bragging rights on who spent the least amount of money in their friend group. From these interviews, they also decided to implement a leaderboard feature and hone in on the specific kinds of data analysis their software project will do.
The group realizes each of their banks has slightly different categories for spending, so they first write a Java file to automatically clean their data so all the categories are standardized (e.g., one person’s spreadsheet has the heading “Restaurants” while another has the heading “Dining Out”, but these mean the same thing).
The group implements their app by using a custom data structure to store transactions. The Transaction Class has the spender’s name, the name of the merchant, the date of the transaction, the transaction category, and the price. They use a custom Binary Search Tree that allows duplicate keys to store all transactions, where the price is the key (so the BST can have multiple $19.99 transactions, for instance). They debate also storing the Transaction objects in person-specific hashtables, so it is faster to access the Transactions for a single person as opposed to having to filter through searching the whole tree–it is storing redundant data, but they decide the trade off is worth it since many of their data analysis features are person-specific. They decide to use Java’s built in mergesort to sort their data.
The group writes in their README what folder to put the spreadsheets in so their Java app can automatically read and clean them. When running the main() method, their software prompts the user to enter a number or letter on their keyboard corresponding to what analysis they want: for instance, pressing L shows the leaderboard of overall lowest spending per person, while pressing R shows each person’s spending on restaurants.
Sample projects from previous semesters include…
These examples hopefully illustrate the scope that is expected for this final project. Depending on your domain, the data cleaning part may be easy (download existing spreadsheets and standardize them) or hard (use complex APIs to extract song information).
For the 10 minutes of lab freely brainstorming either/both:
One suggestion would be to silently write down as many ideas as possible on a sheet of paper for 3 minutes, then pass the paper and iterate on each other’s ideas. Generating individual ideas and then giving "yes, and..." feedback or refining ideas with others can result in more ideas.
If you’re really stuck, you can take a look at the data structures we’ve covered in class and think about how they could be utilized. (I do not recommend this method for real life design work—do not constrain yourself to the technology, or let the technology dictate what is possible. That’s the opposite of human-centered design!)
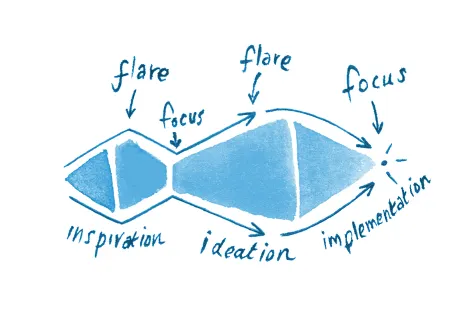
This first step was a "flare" step: generate many ideas and find inspiration. Next, spend 20 minutes with your group coming up with interview questions to further explore promising initial ideas. Time permitting, find someone else in lab today and do a quick interview using your questions.
After lab, each group member should interview at least one other person who is not in this class (e.g., a friend, a colleague, someone who would be most relevant for the domain you’re thinking of). Interviews should take 20-30 minutes and the interviewer should either audio record the interview (to take notes on later) or take notes during it.
The purpose of the interview is to find out more "real life" problems around your proposed domain of software intervention and uncover potentially hidden assumptions. Your interview is not validating if your idea (if you already have one) is a good idea or not, but rather collecting more evidence of activities, problems, and frustrations that are happening in your domain. You can generate abstractions (i.e., that inform your software specifications) from details, but you cannot generate details from abstractions, so try to collect detailed anecdotes from interviewees. Some tips:
After everyone has conducted their interview, meet again as a group. Now is time for the “focus” part of brainstorming: focus your inspirations and ideas into a single project to tackle. Discuss the results and high level takeaways of each interview. During this meeting, take notes on:
Note that these can (and should) be sub-problems: you have only until the end of the semester to actually build your proposal (and we still have one other assignment after Thanksgiving break). Make simplifying assumptions so your project is in-scope for this class, but justify all your assumptions. For instance, if your found problem is that you want to keep track of books checked out on Little Free Libraries across Claremont, when they get removed, when they get returned, and create user profiles to offer recommended books’ locations, it seems hard to track when books get checked out/returned in real time without physically monitoring the locations every day. Why not work on a digital database that lets users browse the books you catalogued (“frozen” at a specific point in time) from the comfort of their computer, letting them traverse a weighted graph with vertices representing the libraries and edges representing the paths between libraries?